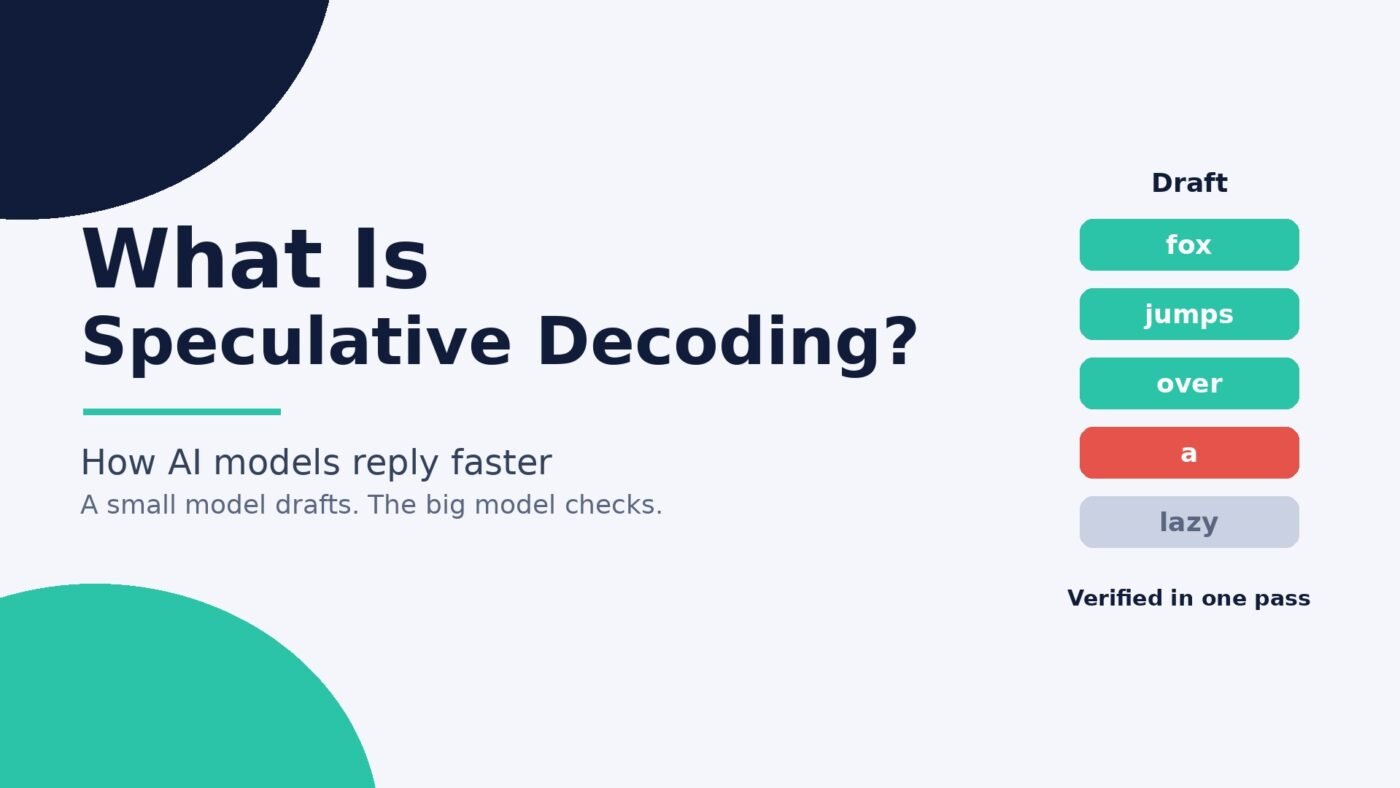
Speculative decoding is a way to make a large language model reply faster without changing what it says: a small, fast “draft” model guesses the next few words, and the big model checks all of those guesses at once, keeping the ones it agrees with. Because the big model still has the final say on every token, the output follows the same distribution it would have produced on its own. In the original 2022 paper from Google researchers, the trick sped up the T5-XXL model by 2X-3X “with identical outputs,” and Google says it now uses speculative decoding to help AI Overviews in Search produce results faster.
This guide explains why chatbots are slow in the first place, how speculative decoding works step by step, the main flavors you will see named in model releases (EAGLE, Medusa, multi-token prediction, prompt lookup), and when it does not help much. No maths required.
Speculative decoding in one sentence
Speculative decoding is an inference speed-up in which a cheap guesser proposes several future tokens and the expensive model verifies them in a single pass, so the expensive model runs fewer times per answer.
A good everyday analogy: a junior assistant types up a draft of the next sentence, and a senior expert reads it. Every word the expert would have written anyway stays. At the first word the expert disagrees with, they cross it out, write their own word, and the assistant starts drafting again from there. The expert never writes faster, but they spend far less time writing word by word.
Why AI chatbots are slow in the first place
A large language model writes its answer one token at a time. A token is a word or part of a word. Google’s researchers give the example that the sentence “One small step for man, one giant leap for mankind” is 12 tokens with a common tokenizer, so the model has to run 12 times to write it. Each token depends on the ones before it, so these runs normally happen strictly in order.
The surprising part is what makes each run slow. It is usually not the maths. It is moving the model’s weights out of memory:
- Each decoding step has to read the whole model’s weights. For the largest models, Google says that can mean reading on the order of a terabyte of data for each word.
- GPUs and TPUs can do far more calculations per second than they can read bytes from memory. Google puts it as hundreds of operations for every byte read, while a transformer doing inference performs only a few operations per byte.
- Hugging Face makes the same point: in text generation, memory bandwidth is the limitation, not the computation itself.
So while the model writes one token, most of the chip’s compute power sits idle. Speculative decoding puts that spare compute to work. Checking five proposed tokens in one pass costs roughly the same memory traffic as generating one, because the weights only have to be loaded once. (If memory and bandwidth are new terms for you, our guide to RAM vs VRAM covers the basics.)
How speculative decoding works, step by step
There are two players. The target model is the big, high-quality model whose answer you actually want. The draft is anything cheap that can guess what the target will say next: a much smaller model, a few extra layers bolted onto the target, or even a simple text-matching rule.
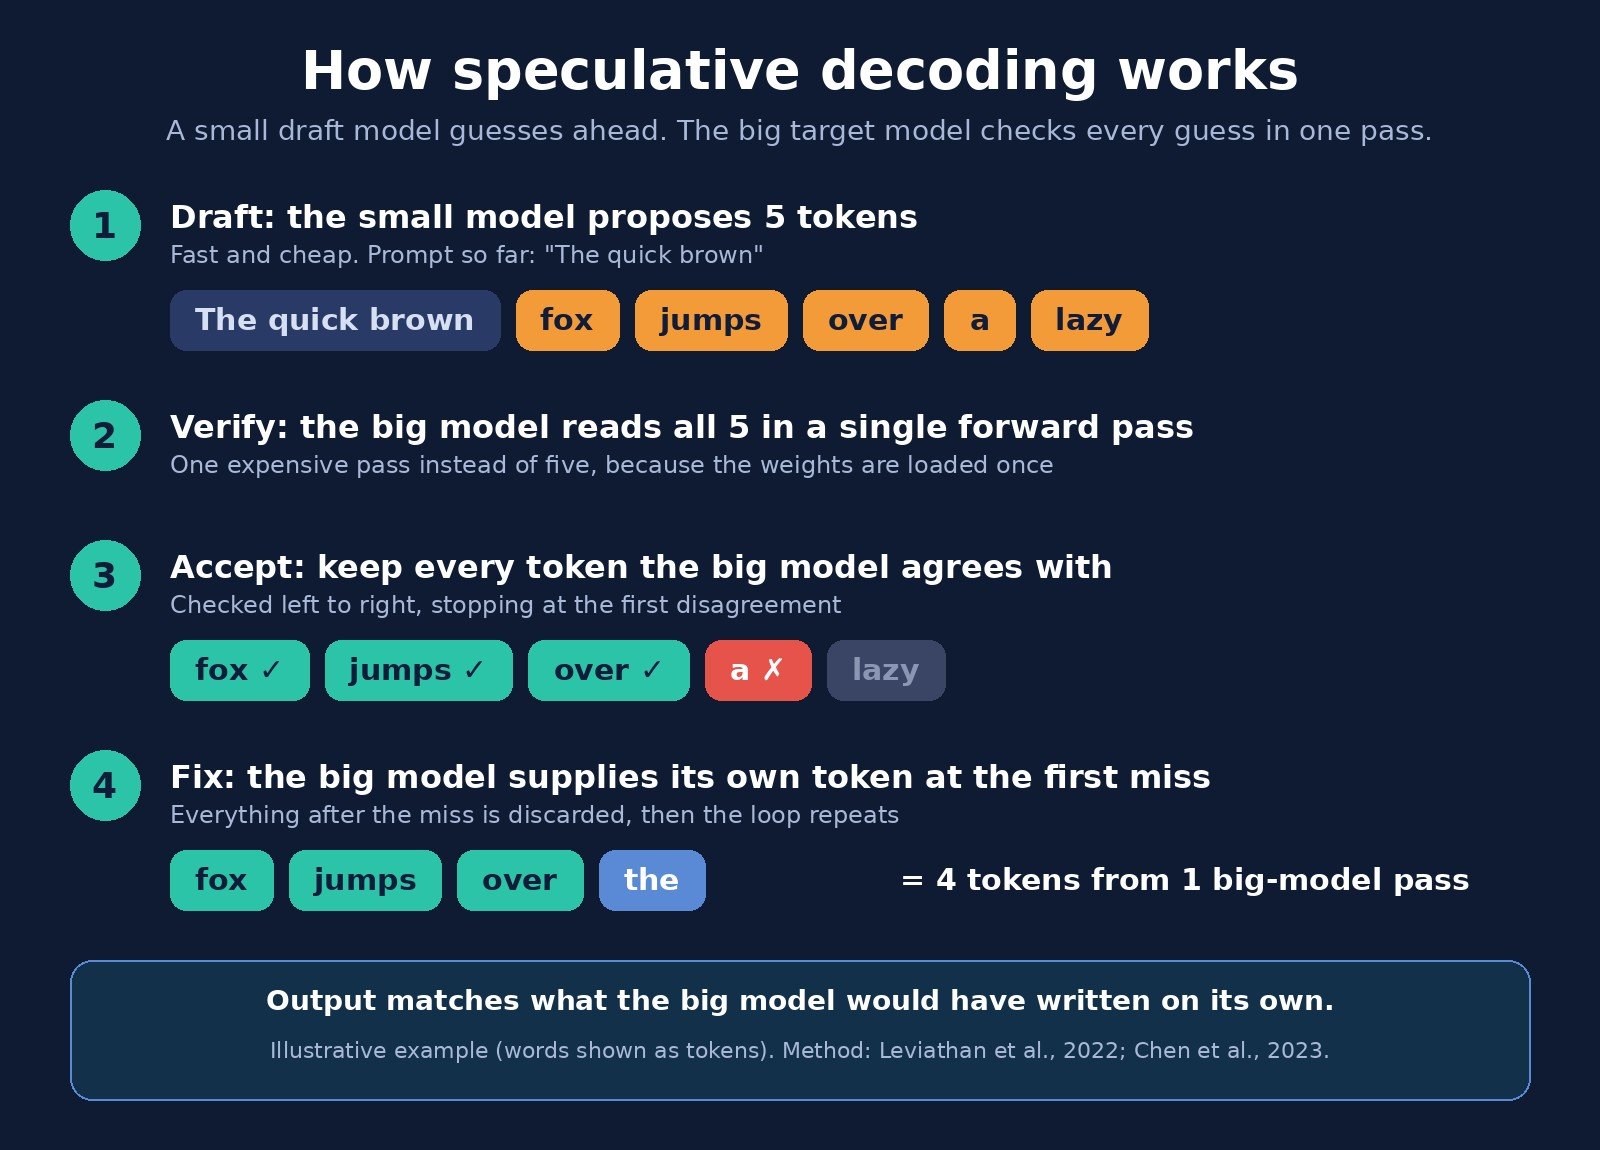
Step 1: Draft a few tokens
The draft quickly proposes a short run of candidate tokens. NVIDIA says drafts are typically 3 to 12 tokens long. Because the draft is small, this is fast.
Step 2: Verify them all in one pass
The target model reads the prompt plus all of the drafted tokens in a single forward pass. A transformer can do this in parallel, and as a side effect it works out what it would have predicted at every position along the draft. This is the key trick: one expensive run now checks several tokens instead of producing just one.
Step 3: Keep the matching prefix
Going left to right, each drafted token is accepted if it is consistent with the target model’s own prediction. With greedy decoding that simply means “the same token.” When the model is sampling (picking among likely tokens with some randomness), the original papers use a modified rejection sampling scheme that accepts or rejects each guess based on how the draft’s and target’s probabilities compare.
Step 4: Fix the first miss and repeat
At the first rejected token, everything after it is thrown away, and the target model supplies its own token for that position, which it already computed during the verification pass. Then the draft starts again from the new end of the text. At worst, if every guess is wrong, the round still produces one token from the target model, the same as normal decoding.
A worked example with timings
NVIDIA’s explainer gives a simple illustration. Suppose one forward pass of a big model takes 200 milliseconds. Writing three tokens the normal way takes three passes, so 600 ms. With speculative decoding, a fast draft proposes two tokens and the big model verifies them in a single, slightly longer 250 ms pass. If both guesses are accepted, the model gets three tokens (the two accepted guesses plus its own next token) in 250 ms instead of 600 ms.
The numbers are illustrative. The more often the draft guesses right, the bigger the saving. The share of drafted tokens that get accepted is called the acceptance rate, and it is the number engineers watch most closely.
Why would a tiny model guess right often? Because a lot of text is easy. Google’s example is “What is the square root of 7? The square root of 7 is 2.646.” Repeating “7” is easy, since the model can just copy it from earlier; producing “2.646” is hard. Google’s researchers argue that small models can handle many of the easy tokens, while the big model is only really needed for the hard ones.
Does speculative decoding change the answers?
In its standard form, no. This is what makes it different from most speed tricks. The 2022 paper describes it as a way to sample from large models faster “without any changes to the outputs”, and DeepMind’s version preserves the distribution of the target model “within hardware numerics.” Every token in the final answer is one the target model approved, and the acceptance rule is designed so that the odds of each token are exactly what the target model alone would have given.
Two honest caveats:
- “Same distribution” is not always “same text.” If the model is sampling with randomness (a temperature above zero), you would get different wording run to run anyway. Speculative decoding keeps the same odds; it does not freeze a specific answer.
- Some variants deliberately relax the guarantee. For example, Hugging Face Transformers offers a “static ensemble verification” option that raises acceptance rates at the cost of making the output distribution a mixture rather than exactly the target model’s. Medusa-2 also fine-tunes the main model together with its draft heads, which changes the model itself. Check which mode a tool uses before assuming it is lossless.
How much faster is speculative decoding?
Reported speed-ups depend heavily on the model, the task, the hardware and how good the draft is. Here is what the main papers report, in their own words and test setups. These are research results, not guarantees for your setup.
| Method (year) | What drafts the tokens | Reported result | Source |
|---|---|---|---|
| Speculative decoding (2022) | Smaller separate model | 2X-3X faster on T5-XXL, identical outputs | Leviathan et al. |
| Speculative sampling (2023) | Smaller separate model | 2-2.5x decoding speed-up on Chinchilla 70B | Chen et al., DeepMind |
| Medusa (2024) | Extra decoding heads on the main model | Over 2.2x (Medusa-1); 2.3-3.6x (Medusa-2) | Cai et al. |
| EAGLE (2024) | Light head reading the model’s internal features | 2.7x-3.5x latency speed-up on LLaMA2-Chat 70B | Li et al. |
| EAGLE-2 (2024) | EAGLE with a dynamic draft tree | 3.05x-4.26x | Li et al. |
| EAGLE-3 (2025) | Head using features from several layers | Up to 6.5x | Li et al. |
| Multi-token prediction in DeepSeek-V3 (2024) | Built-in MTP module predicting the 2nd next token | 85-90% acceptance for the extra token; 1.8x tokens per second | DeepSeek-V3 report |
Real-world tooling tends to be more modest. When Hugging Face launched its version, called assisted generation, it reported up to 3x speed-ups with INT8 and up to 2x otherwise when the model fits in GPU memory, and up to 10x when the model is so big it relies on memory offloading. The same post warns that it is “not a silver bullet” and that you should benchmark before relying on it.
Types of speculative decoding you will see named
All of these share the same draft-then-verify idea. They differ in where the guesses come from.
| Approach | Where guesses come from | Needs extra training? | Good fit |
|---|---|---|---|
| Draft-target (classic) | A separate small model with the same tokenizer | No, if a suitable small model exists | Model families with tiny siblings |
| Prompt lookup / n-gram | Copies of text already in the prompt | No | Summaries, edits, code changes, translation |
| Medusa heads | Extra prediction heads on the main model | Yes, train the heads | Single-model serving |
| EAGLE family | A light head that reads the main model’s hidden states | Yes, train the head | Production serving stacks |
| Multi-token prediction (MTP) | Prediction layers trained into the model checkpoint | Built in by the model maker | Models released with MTP, like DeepSeek-V3 |
| Self-speculative (early exit) | The model’s own early layers | Model must be trained for early exit | Saving memory: one model, no second copy |
Classic draft model
This is the original design: pair a big model with a small one from the same family. In Google’s paper, a 60M-parameter T5-small drafting for the 11B-parameter T5-XXL on a translation task gave about a 3x speed-up. Hugging Face says the assistant should be at least an order of magnitude smaller than the main model and use the same tokenizer, although it also offers a “universal” mode for mismatched tokenizers.
Prompt lookup (n-gram) decoding
No second model at all. The system looks for a run of tokens in the prompt that matches what was just written and proposes the words that followed it. Hugging Face notes this suits input-grounded tasks like summarization and translation, where the answer often repeats the source text.
Medusa and EAGLE
Running and maintaining a second model is a hassle, which is the problem Medusa set out to fix by adding extra heads to the main model that predict several upcoming tokens. EAGLE goes a step further: its draft head looks at the main model’s internal features rather than just the text. NVIDIA describes the EAGLE head as a lightweight transformer decoder layer followed by a final linear layer, and EAGLE-3 builds a tree of possible continuations that the main model checks at once.
Multi-token prediction
Some models are trained from the start to predict more than one token ahead. DeepSeek-V3 predicts the next two tokens and pairs that with speculative decoding, reporting 1.8 times the tokens per second. Hugging Face lists DeepSeek-V3 and GLM-4.5 as checkpoints that carry MTP weights. If you follow AI news, this is the kind of “speculative-decoding trick” behind headlines such as DeepSeek’s open-sourced DeepInfer engine.
When speculative decoding does not help much
- The draft guesses badly. Every rejected token is wasted work. Hugging Face puts it plainly: a poor-quality assistant gives you the cost of using the assistant with little to no benefit, and a slow assistant can cause a net slowdown.
- Very creative, high-randomness output. Higher temperatures make the next token harder to predict. Hugging Face found that low temperatures are more favorable to the assistant and keep most of the latency benefit.
- Busy servers with big batches. Speculative decoding is mainly a latency fix for using idle compute. When a server is already batching many users together, there is less idle compute to borrow. EAGLE-3’s authors report up to 6.5x in their tests but a 1.38x throughput improvement at a batch size of 64 in the SGLang framework. Hugging Face Transformers’ built-in version also does not support batched inputs.
- Extra memory. A separate draft model has to sit in memory next to the main one. On a home GPU where the main model barely fits, that can be a deal breaker. Self-speculative and MTP methods avoid a second copy.
Speculative decoding vs other ways to make AI faster
People often lump these together. They solve different problems and are usually combined.
| Technique | What it changes | Does output change? | Main win |
|---|---|---|---|
| Speculative decoding | How tokens are generated (draft + verify) | No, in its standard form | Lower latency per reply |
| Quantization | Stores weights with fewer bits | Slightly, usually small | Less memory, faster loading |
| Knowledge distillation | Trains a smaller student to copy a big model | Yes, it is a different model | Cheaper model overall |
| Using a smaller model | Swaps in a smaller model entirely | Yes, usually lower quality | Speed and cost |
| Mixture of experts | Model design that activates only part of the network per token | It is how the model works | Less compute per token |
They stack well. Hugging Face measured its biggest in-memory gains from assisted generation when combined with INT8 quantization, and distilled small models make natural drafters for their bigger siblings. Speculative decoding is the only one on this list that speeds up a model without changing the model or its answers.
Where you will run into it
- Search and chat products. Google says speculative decoding remains a significant part of the optimizations behind AI Overviews and is used in a number of its products.
- Serving software. NVIDIA points developers to TensorRT-LLM, SGLang and vLLM for deploying it, and Hugging Face Transformers exposes it through an
assistant_modelsetting in generate().
For most people, the effect is simple: answers stream onto the screen in quicker bursts instead of word by word. If you run models locally, it is worth testing a small sibling model as a draft, but measure the speed on your own prompts, since gains vary a lot by task.
Frequently asked questions
What is speculative decoding in simple terms?
Speculative decoding is a technique that makes a large language model generate text faster. A small, fast model guesses the next few tokens, and the large model checks all of those guesses in a single pass. The large model keeps the guesses it agrees with and corrects the first one it does not, so the final answer is what the large model would have produced on its own.
Does speculative decoding reduce quality?
Standard speculative decoding does not reduce quality. Every token is verified by the large model, and the acceptance rule keeps the output distribution identical to normal decoding, as shown in the original paper. Some variants trade a little exactness for speed, so check whether a tool calls its method lossless.
How much faster is speculative decoding?
Research papers commonly report about 2x to 3x faster generation, and newer methods such as EAGLE-3 report up to 6.5x in their tests. Real gains depend on how often the draft guesses correctly, the task, the hardware and how many users the server is handling at once.
What is a draft model?
A draft model is the small, fast model that proposes candidate tokens in speculative decoding. It is usually a much smaller model from the same family that shares the main model’s tokenizer. Some methods replace it with extra heads on the main model (Medusa, EAGLE), built-in multi-token prediction layers, or simple text matching from the prompt.
What is the difference between speculative decoding and speculative sampling?
They are closely related names for the same draft-and-verify idea, published around the same time by Google (speculative decoding) and DeepMind (speculative sampling). Google’s researchers describe speculative sampling as the general method for accepting or rejecting random guesses, and speculative decoding as its application to language models.
Is speculative decoding the same as quantization?
No. Quantization shrinks a model by storing its weights with fewer bits, which can slightly change its answers. Speculative decoding leaves the model untouched and only changes how tokens are produced. The two are often used together.
The bottom line
Speculative decoding exploits a quirk of AI hardware: generating one token at a time leaves most of a GPU’s compute idle, because the real bottleneck is reading the model’s weights from memory. By letting something cheap guess ahead and having the big model check several guesses at once, it cuts the number of slow passes, often by 2x to 3x in published tests, without changing what the model would say. It works best when the draft guesses well, the text is predictable and the server is not already packed with requests. To go deeper on the surrounding ideas, start with our explainers on AI inference, the transformer model and LoRA fine-tuning.

The Teck Hustlers Editorial Team covers technology, business, finance and gaming news for readers who want the story behind the headline. Every article is researched, written and edited by our in-house team, checked against company announcements, filings and reputable reporting, and updated when new facts emerge. We focus on what each development means for founders, professionals, investors and everyday users. Have a tip or a correction? Reach us through our contact page.