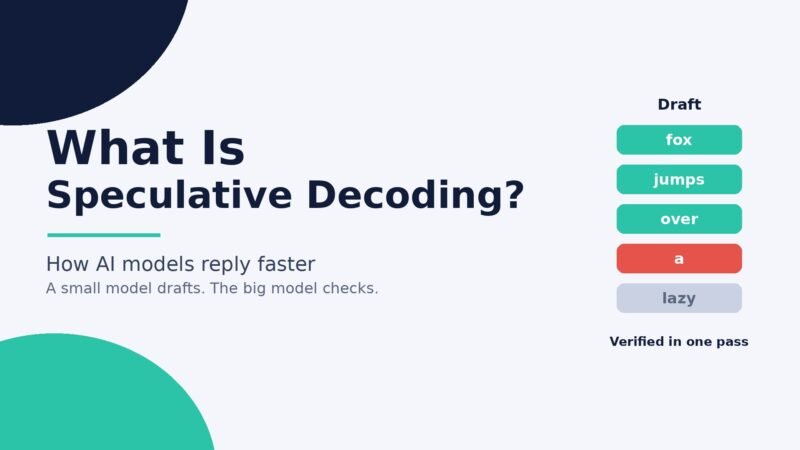

What Is Speculative Decoding? How AI Models Reply Faster Without Losing Quality
Speculative decoding lets a small draft model guess the next few tokens while a large AI model checks them all…
Teck Hustlers Where tech meets hustle!
Speculative decoding lets a small draft model guess the next few tokens while a large AI model checks them all…
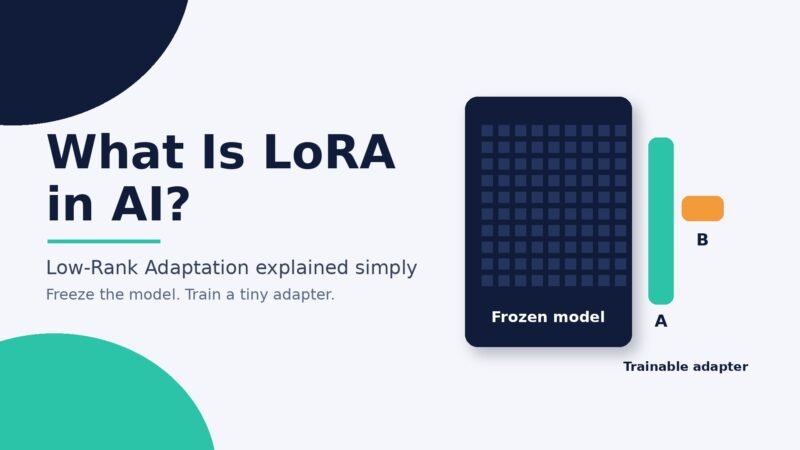
LoRA (Low-Rank Adaptation) fine-tunes an AI model by freezing its weights and training two small adapter matrices. How it works,…
Claude Fable 5.2 and Mythos 5.2 are Anthropic's new frontier models: up to 30% faster, $8/$40 per million tokens and…
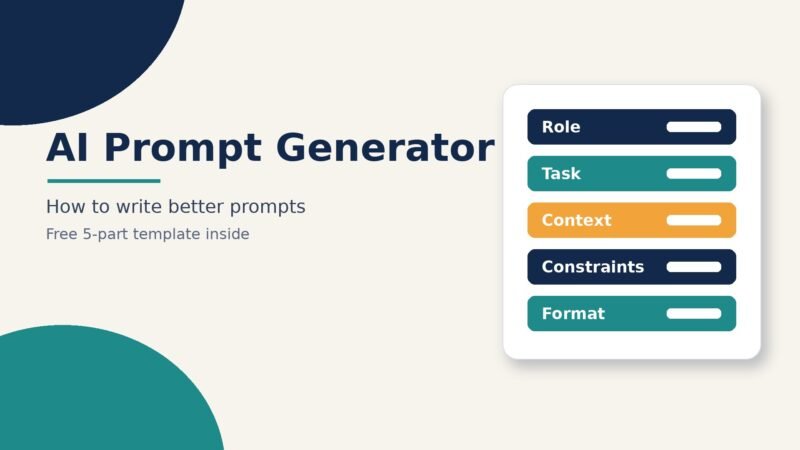
What an AI prompt generator really does, when it helps and when it pads, plus a free five-part template and…
What is prompt injection? It is an attack where text slipped into an AI's input overrides its instructions. Learn direct…
A Siri AI agent could arrive as early as 2027, per Bloomberg's Mark Gurman, after Apple CEO John Ternus reportedly…
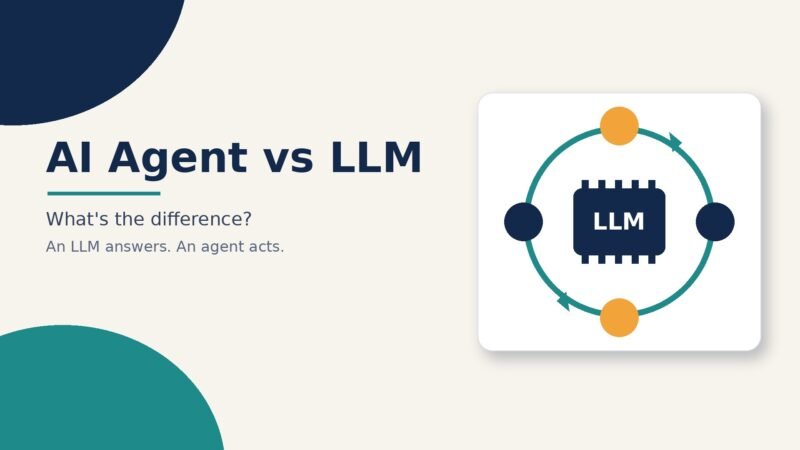
An LLM writes a response and stops; an AI agent uses an LLM to plan, call tools, check results and…
What is prompt chaining? It splits a complex AI task into a sequence of prompts where each output feeds the…
Anthropic gas generators deal: the Claude maker reportedly paid about $3.4 billion for 1.7 GW of Caterpillar generator orders from…
What is few-shot prompting? Learn how adding two to five examples to a prompt steers ChatGPT, Claude and Gemini, how…